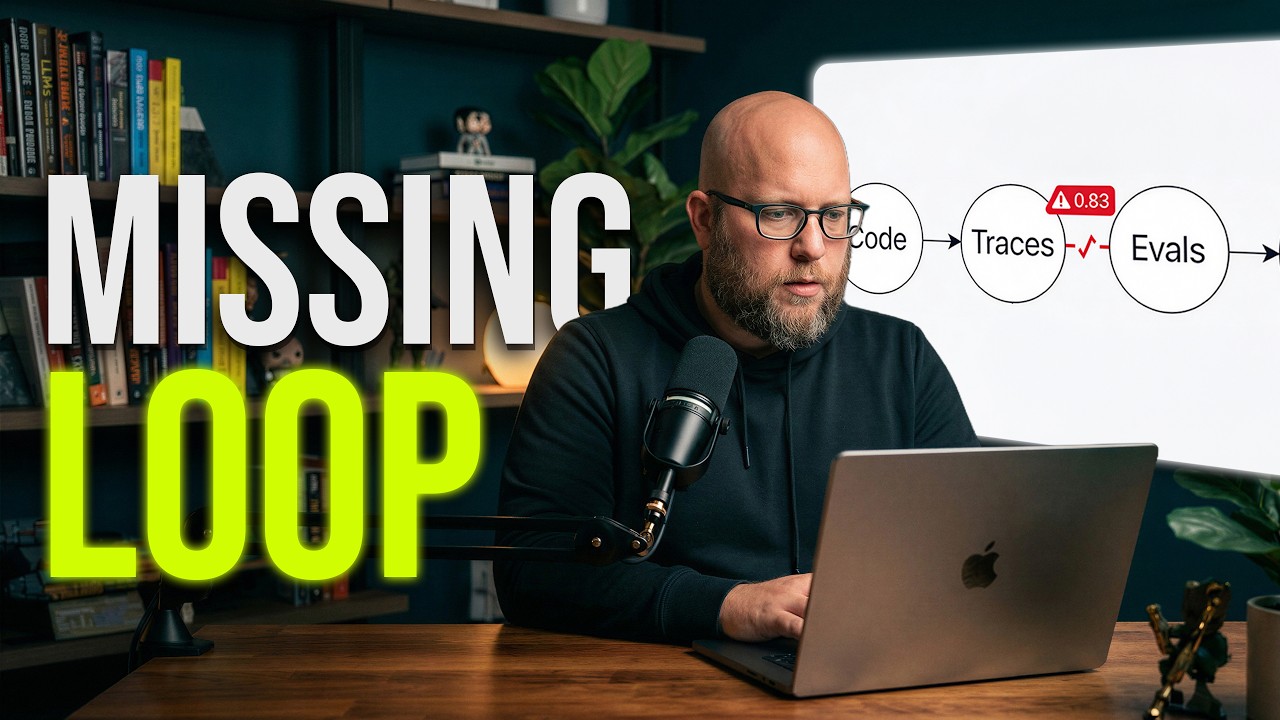
Traces tell you what your agent did. Evals tell you whether it did it right. Most AI agent stacks ship with neither connected to the other — and that’s how a “successful” run can quietly include a fabricated action item your unit tests would never flag.
The Agent Quality Loop, end to end
This is Part 3 of the Agent Quality series, closing the loop between Part 1 on the eval framework and Part 2 on agent observability. The loop: code → traces → evals → scores → back to code. Each piece is well-known in isolation. The point of this video is to wire them together on a real agent and watch the flywheel turn.
A custom LLM-as-judge scorer in Mastra Studio
I add a custom groundedness scorer to a Mastra meeting assistant using createScorer, following the preprocess → analyze → generateScore → generateReason pattern. The scorer is attached to the agent so every run gets graded automatically. Mastra Studio shows the trace and the score in one place. First run: 0.83, one action item that didn’t appear in the transcript. I fix the prompt with explicit grounding rules and the score moves to 1.00. No custom infrastructure — observability and evals both ship in Mastra.
Why this fails without the loop
Underspecified prompts produce plausible-looking failures. The agent looks like it worked. The logs are clean. The dashboard is green. The only thing that catches the failure is a scorer that checks the output against the input — and the only way to fix it without guessing is to read the trace.
If you’re shipping AI agents to production, this is the layer that separates “demo works” from “actually working.” Use the Agent Eval Scorecard to see which layers your current quality loop is missing, then I can help teams build agent quality into their stack from the start.
Free resource
Agent Eval Scorecard
Most teams ship agents based on 'it ran without errors.' Score yourself across the four layers of agent evaluation in two minutes — and find out where your quality gaps are before your users do.
Work with me
Building an AI agent?
I help teams design and ship agentic systems — from architecture to production.